Sub-50ms Usage Checks for AI Credit Enforcement
Real-time credit checks stop runaway AI usage before it happens, not after the bill arrives.
The flat-rate era of AI tooling ended on a specific date. GitHub's move to AI Credits on June 1, 2026 replaced premium request units with token-metered billing across inputs, outputs, and cached context, and the shift made clear that usage, not a subscription tier, now sets the bill. Once billing runs on tokens rather than seats, every inference call becomes a debit against a real balance, and that balance has to be checked before the model runs, not after the invoice lands. The "meter shock" coverage that followed Copilot's June 2026 transition showed what happens when enforcement runs after the fact: developers found out about consumption overruns only once the damage was already billed, with no signal along the way. The failure mode that makes this intolerable at scale is mundane rather than dramatic: one malformed prompt triggers 47 retries, and nobody notices until the invoice jumps. Credit billing turns that kind of accident from an annoyance into a line item, and it's why enforcement had to move inline rather than live in a dashboard checked after the fact.
The right enforcement budget: 50ms, given how long inference takes
The 50ms enforcement ceiling isn't a number chosen for its roundness. It comes directly from how long model inference already takes, so a well-built enforcement layer adds nothing a user can actually feel. LLM inference runs 500ms to 5 seconds per call, and a gateway that adds 50ms of overhead sits below the noise floor of that call, so user-visible latency stays the same. That math matters because it removes the one argument that used to justify pushing enforcement out of band: when gateway overhead ran 200ms or higher, a latency-sensitive team had a real reason to skip inline checks. At 50ms, that reason is gone. The enforcement decision doesn't get added on top of inference time; it occupies the decision window that already exists between the request leaving the client and the model beginning to generate tokens. That distinction carries a sharper implication: a team running 200ms of gateway overhead isn't enforcing anything, because by the time a check that slow completes, the request has already gone through to the model, and what's left is logging. Enforcement that can't stop the call before it happens is just a more expensive way of writing down what already occurred.
What out-of-band enforcement fails to stop
Out-of-band enforcement, a system that samples an audit log, polls on an interval, or reviews spend at invoice time, cannot prevent an overrun because by the time it flags a violation, the compute has already run and the tokens are already spent. Consider an agent set loose on a repository sweep, or a developer mid-refactor who accidentally triggers thousands of completions in a single session: either can drain a credit balance in seconds, and a system that checks balances on an interval only confirms the damage after it's done. The Copilot billing model illustrates the stakes directly: every interaction, from a single-line autocomplete to a full agentic sweep, consumes credits in proportion to tokens processed, and without an inline check, the balance is a historical record rather than something that actually controls what happens next. Security research backs up the underlying logic. Mandiant's M-Trends 2026 report measured a 22-second machine-speed attack tempo, and detection running on three-second intervals still fails to prevent damage, because you have to make the decision before the request ever reaches the model. Credit exhaustion follows the same clock. Out-of-band review also runs against what the NIST AI RMF's MEASURE function expects in continuous monitoring: when a monitoring approach meaningfully slows the system down, teams tend to sample instead of watching every request, while a sub-50ms check can run against every single request at full production rate. The obvious objection, that an inline check could itself fail and block legitimate traffic, has a real answer rather than a reason to abandon the approach: a configurable fail-open or fail-closed posture, built into the architecture itself.
Anatomy of a Sub-50ms Enforcement Check
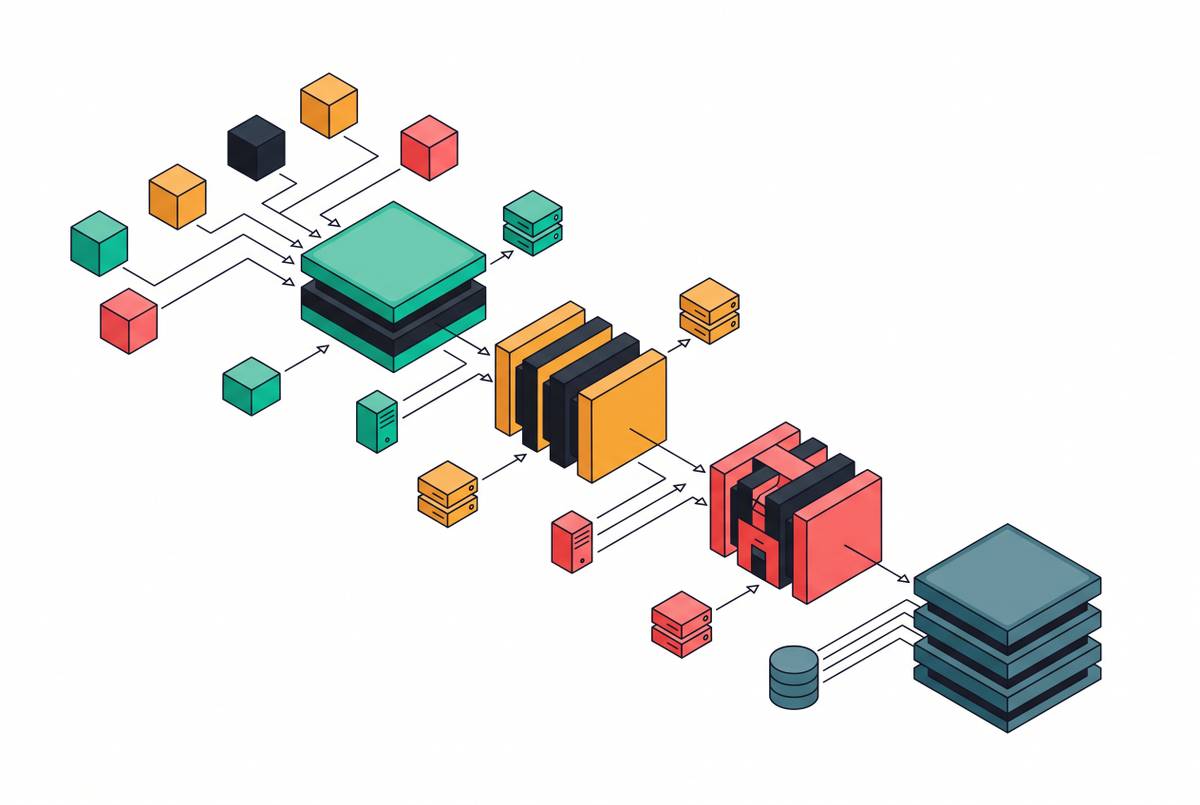
Hitting 50ms consistently isn't one engineering decision, it's four: identity resolution, balance read, policy evaluation, and audit write, each with a fast path and a slow path, and the gap between them is where most of the budget gets lost or saved. Tracing a warm gateway through a single request shows where each millisecond goes. The TLS handshake and HTTP parse cost a few milliseconds when connections stay pooled rather than reopening fresh each time. Identity validation against a cached identity-provider token runs one to two milliseconds, as long as that validation happens locally rather than over the network. Classifying the content of a prompt, when done with a deterministic classifier running on prompts in the thousand-token range, finishes well inside the remaining budget. Policy evaluation against cached rules adds another one to two milliseconds. Serializing and dispatching the audit record costs a few more milliseconds, provided the write path doesn't block. What's left is the actual model call upstream, and the gateway doesn't add to that time beyond the wire itself.
None of this holds without one condition: the gateway needs cached policy compilation, cached identity-provider keys, and classifier model weights already sitting in memory. The first request after a cold start pays a one-time cost that a warm fleet never has to pay again. Two details decide whether the whole budget survives contact with production. The balance read has to come from memory or a low-latency store, because a synchronous round-trip to a relational database for the current balance is the single most common way teams blow past 50ms without realizing it. The audit write has to be non-blocking: the decision gets recorded before the model's response returns to the user, and the durable flush to storage happens asynchronously afterward. If that audit commit sits in the critical path instead, whatever latency the storage layer has becomes latency the user feels directly. Policy evaluation has to run locally for the same reason. Calling out to a remote authorization service on every request means the round-trip to that service dominates the entire budget, and the fix is to compile the policy rules down to a deterministic evaluator that runs in-process rather than over a network.
The four patterns that silently push enforcement latency above 50ms
Most of the time, enforcement latency doesn't blow past 50ms because of some deep architectural flaw. It happens because of four specific habits, each with a direct fix. The first is calling a remote service for every authorization decision: the round-trip dominates the whole budget, and the fix is compiling policy locally so the gateway evaluates rules in-process instead of asking somewhere else. The second is a synchronous audit write: if the commit to the audit record blocks the response, latency in the storage layer becomes visible directly in what the user experiences, and the fix is committing to a fast write path that flushes to durable storage asynchronously. The third is a cold classifier path: a data-classification model that loads itself on the first request, or that calls out to a remote classifier service, produces latency that varies unpredictably request to request, and the fix is keeping classifier weights in memory with a warm-up step built into startup. The fourth is DNS lookup overhead and TLS re-establishment: resolving the upstream model API's hostname fresh on every request, and re-establishing a TLS connection each time, adds a steady tax that DNS caching at the gateway and connection keep-alive on both the inbound and upstream sides remove entirely. What ties all four together is that each one puts a network round-trip or a blocking write somewhere that should be fully local and async. The fix is never to make the slow operation faster, but to take it off the critical path altogether.
The async event pipeline underneath the enforcement layer
Enforcement and billing are two different jobs, and they can't share a critical path. The enforcement check reads a cached balance synchronously, in the few milliseconds described above, while the durable record of what actually happened flows through an asynchronous event pipeline on its own schedule. In a standard metering setup, the service emits a raw event to a Kafka topic, and a dedicated metering microservice consumes that stream and processes it independently, so the user-facing service never waits around for metering to acknowledge anything. Kafka's own throughput numbers explain why this works as infrastructure: it handles millions of events per second with latencies as low as 2ms, scales horizontally, and keeps data durable through replication, so the pipeline itself never becomes the thing slowing requests down. The separation between enforcement and billing matters architecturally, not just technically. A billing or monetization team can change pricing logic without coordinating a deployment with the team that owns the core product, because the event stream is the stable interface between them, not a shared codebase.
What closes the loop is one coordinated, not shared, operation: the platform checks a customer's balance before an AI action runs, and once the action completes, usage gets submitted, priced, and debited from that balance as a single operation. The enforcement read and the ledger write stay coordinated with each other without sitting on the same execution path. This also means the rating engine has to run continuously rather than in nightly batches, because a customer who needs to know they're approaching a budget in real time gets no value from a number that updates once a day. Some teams split the responsibility in a specific way: they own the event pipeline itself, since infrastructure like Kafka and ClickHouse is usually already serving analytics and anomaly detection elsewhere in the stack, and they bring in a separate billing layer that sits on top of that pipeline. That split is a reasonable middle path precisely because the pipeline is infrastructure the team needed regardless of billing.
Real-time balance enforcement from the user's side
Inline enforcement does more than stop overruns before they happen. It gives both the vendor and the customer a live control surface over AI spend, visible before the costs pile up. The UsageFlow runtime enforcement model shows the full sequence in practice: record the user's intent, check that intent against policy and a live balance (say, a customer approaching their spending cap), transform the request if needed (dropping from opus-4 with high reasoning down to haiku with low reasoning, turning off browser access, capping tokens lower), and explain the change to the customer, all before the model call ever executes. That intent-policy-transform-explain sequence only works because the enforcement check completes fast enough to sit in front of the model call without the user noticing any delay. It turns the enforcement layer from a blunt gate into something closer to a negotiation, one that keeps the user's request alive at a lower cost rather than simply rejecting it once a budget runs thin.
The same logic explains why real-time spend visibility, when it shows up as a product feature, doesn't come down to a dashboard. It's a direct consequence of the enforcement check running against a live balance in the first place, since any number the enforcement layer can check, it can also show the customer as the request happens. Atlassian's pricing structure shows the stakes concretely: standard plans include 25 Rovo AI credits per user each month, and products like the Virtual Service Agency can add charges of $0.30 per conversation once usage runs past what's included. Without an inline check, a customer on that plan gets no signal in the moment the overage begins; the first indication is the bill. The same risk occurs on the developer side. If a developer refactoring a legacy module generates completions at a rate far above their normal pace for a single day, and no monitoring ties directly to enforcement, that spend stays invisible until the invoice arrives weeks later.
The GeekyAnts Fraud Engine: Proving the 50ms Decision Architecture at Production Load
The architecture behind sub-50ms credit enforcement isn't speculative, because a comparable decision problem has already been solved at production scale in a different domain with the same latency pressure. GeekyAnts built an Autonomous Multi-Agent Pipeline that looks at a financial transaction as it happens and decides whether to approve it, challenge it, or block it. Fraud detection and credit enforcement are solving structurally the same problem: a system has to make a binary or near-binary decision about whether to let an action proceed, using information that's already cached or locally available, inside a window measured in milliseconds rather than seconds. A fraud engine that can't render a verdict before the transaction clears is as useless as a credit check that can't render a verdict before the model call starts. That a production fraud pipeline runs this pattern under real transaction volume, rather than as a proof of concept, is the strongest evidence that the fast-path, cache-first, async-audit architecture described above is an architecture that already holds up where the cost of a late decision is measured directly in money lost, not just in a slightly larger invoice.
Sources
- AI Gateway Sub-50ms Latency: What the Number Actually Buys You
- UsageFlow — AI Runtime Billing Infrastructure
- Copilot to Usage Billing June 1, 2026: AI Credits, Token Costs, and Meter Shock - Windows News
- How Do AI Companies Bill for Token Usage? A Guide to Metering & Rating Infrastructure
- A Real-Time AI Fraud Decision Engine Under 50ms - GeekyAnts