Deduplication Strategies for Duplicate Usage Events at Scale
Stable identities and retry windows prevent duplicate charges in distributed billing systems.
Duplicate usage events are a structural property of distributed billing. Deduplication at scale therefore requires more than a check at the API boundary. Stable event identity, a retry-aware deduplication window, and idempotent processing at every stage must work together so each business action is counted once without discarding distinct usage.
Why duplicate usage events are structurally inevitable in any distributed billing pipeline
A producer sends a usage event, waits for a response, and times out. It cannot tell if the request failed or the acknowledgment was lost. The server may already have processed the event successfully, so a retry submits the same usage again. Not retrying leaves the opposite risk unresolved, because the first request may never have arrived. Reliable billing must accommodate both outcomes.
Other failure paths create the same ambiguity. A load-balanced ingest node can fail while writing, so a retry can reach a sibling node and create a second record. An at-least-once queue redelivers a message when its acknowledgment misses the visibility timeout. A worker can process a batch, crash before committing its offset, and replay that batch after restarting. Operators can also resend events during recovery without knowing if the original events were processed. These are independent sources of duplication.
Exactly-once delivery across a network is not a practical guarantee. The viable pattern is at-least-once delivery with exactly-once processing at the meter. Counting duplicates overcharges customers and creates invoice disputes, credit notes, and distrust, while dropping distinct events as false positives leaks revenue. Correcting an overcharge does not erase the procurement scrutiny it creates.
Between June 1 and July 20, 2026, GitHub, OpenAI, and Anthropic migrated flagship products to credit-based metering. GitHub Copilot introduced AI Credits with token-based drawdown and free completions, while ChatGPT Workspace Agents added credits on top of seats. Anthropic’s Fable 5 began a temporary shift to usage-credit billing because of capacity limits beginning July 7–20 for Pro and standard seats, while Max and premium seats kept their included access. A duplicate that consumes prepaid balance becomes a product-level problem immediately and requires a manual adjustment to correct.
Why idempotency keys must be deterministic and client-assigned, not server-generated
A server-assigned UUID seems to give each event a clear identity. It identifies an arrival, however, rather than necessarily identifying the business action behind it. If a producer generates a fresh random UUID each time it sends, a retry reaches the meter with a different key. Both records look new to the deduplication layer.
Identity must instead originate with the producer. The key should be derived from the request ID and event type when the business action is decided, before the send loop begins. Every retry of that action then presents the same key, including when the server never saw the first attempt. Genuinely distinct actions must receive distinct identities. The meter cannot safely infer whether two uses of one event ID represent a retry or separate billable activity.
The endpoint must enforce that distinction through its API contract. When a key already exists and the request-body hash matches, it returns the cached response without processing the event again. When the key exists but the hash differs, it returns a conflict error. That difference exposes a producer error explicitly. Silently accepting one body would conceal the reuse of an identity across different events.
Concurrency makes atomicity essential to this contract. A read followed by a separate write allows concurrent retries to pass the existence check before either has recorded the key. Atomic Redis operations are a standard tool for closing that race, including a Lua script that checks existence and performs set-if-absent in one operation. Request fingerprinting and atomic key registration solve different problems.
How to size and structure the deduplication window so legitimate retries are never dropped
A stable key works only while the system remembers it. Once the deduplication window expires, a retry can pass as new usage and inflate the bill. The governing rule is therefore to exceed every producer’s maximum retry horizon with margin. Window length is both a storage setting and a billing decision. Without the original event log, downstream reconciliation cannot bring back the missing evidence.
That timing assumption belongs in the runbook. A producer’s retry-policy change must trigger a review of the deduplication window, because the coupling otherwise breaks silently. Platform acceptance windows also constrain what the pipeline can submit. An internal policy that permits older retries cannot override a downstream platform’s timestamp restrictions.
At moderate volume, a relational unique index on (tenant, source, event_id) is the simplest starting point. The database rejects conflicting inserts transactionally, without requiring application code to enforce uniqueness. As volume grows, a key-value store with set-if-absent and TTL can provide a more scalable deduplication store. Capacity planning then becomes part of correctness. If memory pressure evicts a key before its TTL runs out, a later retry passes the check even though it arrives within the promised window.
The migration path need not discard the original identity scheme. Teams can begin with a relational index and move to a key-value TTL store as volume grows, provided the schema anticipates that transition. If a pipeline already uses a log-compacted system, compaction by key is another option. It retains the latest value for each key, trading write latency for the operational simplicity of avoiding a separate store. The choice changes where deduplication state lives while leaving the required duration of retry protection unchanged.
Why multi-stage deduplication catches what single-layer checks miss
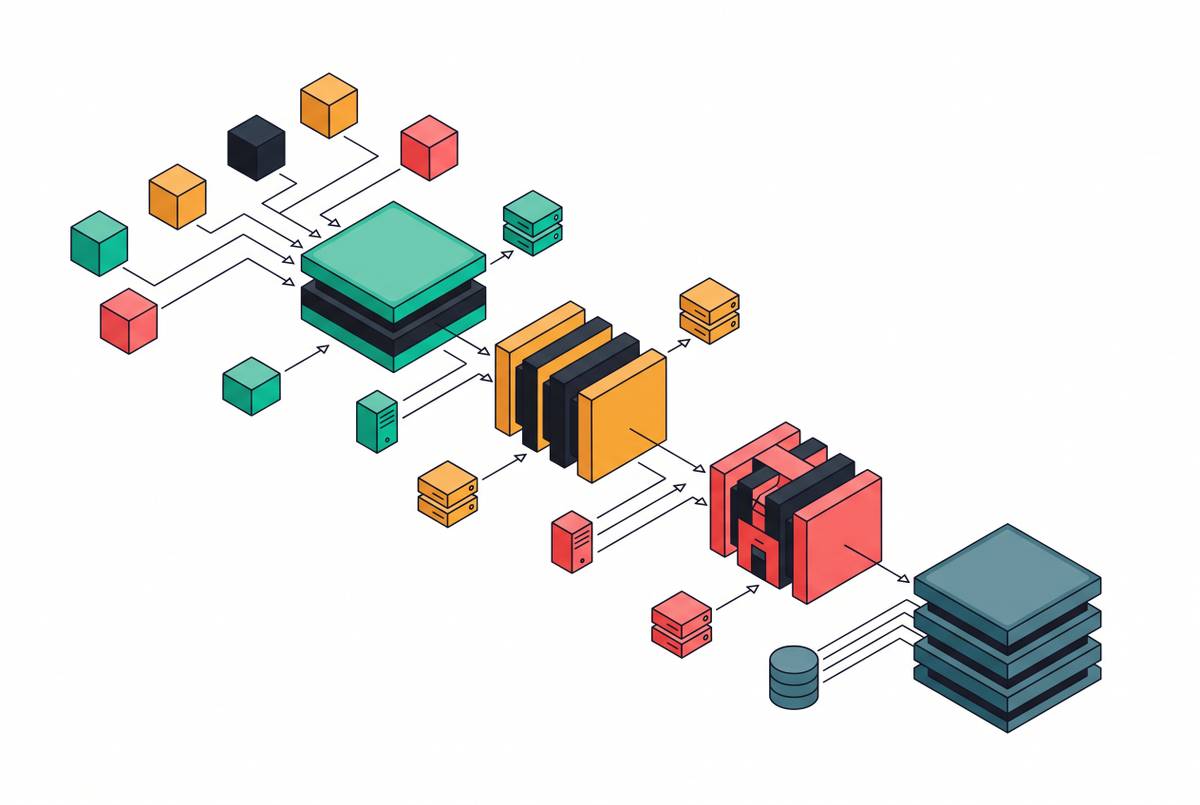
An ingest check protects against producer retries. It does not protect against duplicates created after admission, because queue redelivery, worker retries, and multi-node fan-out need not revisit the API boundary. A pipeline can therefore have a correct endpoint and still double-count usage. Each processing boundary where an already-admitted event can be applied again needs its own protection.
At the queue layer, consumers must check deduplication state before they process a message, since the same message can arrive more than once. At aggregation, the same principle applies to the job’s output. A crash-and-restart can rerun an aggregation over events that workers processed correctly. Writing results with a unique constraint keyed on the aggregation window and tenant makes that step idempotent.
Identity scope also affects security. Including the tenant and event source in the deduplication key prevents independently generated event IDs from colliding across those boundaries. Credentials must be scoped so that a service authorized for Tenant A cannot report usage for Tenant B. Authentication belongs at the ingest endpoint. A payload field claiming a tenant ID is not equivalent to a credential authorized for that tenant.
An anomalous event rate can indicate either a compromised source or a runaway retry loop. Rate limits surface both before they reach aggregation, while source-scoped keys keep their identities separate from other services’ events. These controls have distinct roles in the pipeline. Authentication governs who may report usage, deduplication governs whether it has already been counted, and rate limits constrain abnormal submission volume.
How to handle late-arriving events without corrupting closed billing periods
A late event may be the first report of genuine usage whose billing period has already closed. Discarding it as old loses revenue, while assigning it by arrival time can place the charge in the wrong period. Deduplication establishes event identity.
Event-time timestamps provide the missing information. The producer attaches the timestamp when the action occurs, allowing billing to distinguish that moment from ingestion hours or days later. Billing on ingestion time instead assigns usage to the period in which the pipeline received it. Stable identity and event time therefore serve complementary purposes. One recognizes repeated delivery, while the other establishes the usage period.
Teams need a written policy for events that arrive after finalization. The available approaches are to roll them into the current open period or issue a correction against the closed one. Consistent application is more important than leaving the choice to incident-by-incident judgment, which creates disputes. An incremental counter cannot support this reliably on its own. It records a total but not the events within it, so an audit cannot reconstruct the sequence or retroactively assign a late event to its correct period.
Why persisting raw events rather than counters is the architectural choice that makes everything else work
Updating a total saves the work of keeping and processing every record behind it, but billing needs evidence that the total alone cannot give. Without event records, the system cannot establish which usage was already counted, explain an invoice line item, or reconstruct a correction.
A rating bug makes that loss concrete. Correcting an incorrectly applied pricing rule requires the original events so the system can replay them under the right rule. Without those records, the remaining option is a manual adjustment that is not auditable and does not scale. An enterprise customer asking for the usage behind a charge needs an event-level view.
Product teams can simulate a new pricing tier against historical events to see what existing customers would have paid. That benefit does not make indefinite hot storage economical at extreme volume. Tiered retention addresses the cost directly. A hot store supports the deduplication window, a warm store supports the billing period, and a cold archive preserves records for audit.
The eventId field and unique constraint on (tenant, source, event_id) must exist before the first production event is written. Adding them later requires backfilling or accepting a gap in deduplication guarantees during migration. At low volume, a Postgres unique constraint is sufficient, while tens of millions of events per month require a streaming pipeline with idempotent writes. At hundreds of millions, the architecture changes further, but the original event identity schema can survive those transitions.
When to build the deduplication pipeline in-house and when to buy infrastructure that has already solved it
An in-house pipeline is justified when the billing model is structurally unsupported by available platforms, data residency requirements exclude managed deployment, or extreme volume makes platform fees exceed engineering costs. These are demanding conditions, and most teams do not meet them. An unsuccessful platform search is not proof that a pricing model cannot be expressed. Teams must also compare the costs of owning the pipeline for as long as it runs, including the work after the first build. Deduplication remains an operating responsibility after launch.
That responsibility consumes a meaningful fraction of a senior engineer’s time. Upgrades, incident response, and schema migrations continue as pricing evolves, even when the original pipeline works correctly. Residency requirements can still make that investment necessary, particularly where on-premises or sovereign-cloud deployment is mandated. Extreme volume can also justify it economically. In either case, the relevant comparison is against the fully loaded cost of building and maintaining the pipeline permanently.
Teams that already run Kafka and ClickHouse for analytics and anomaly detection may own the event pipeline and buy the billing layer above it. Funding already in place for infrastructure changes how much that split costs. It does not remove the interface responsibility. The boundary between metering and billing still needs maintenance, testing, and debugging as the systems evolve independently.
Purpose-built infrastructure takes less work to connect when it has deduplication, late-arrival windows, and multi-dimensional pricing built in. For AI products, those dimensions can include tokens, GPU-minutes, audio minutes, and hardware tiers, while prepaid credit wallets must coexist with postpaid invoices. Assembling separate tools leaves permanent engineering ownership of the glue between them. The build-versus-buy choice depends on whether taking on that work meets a real need of the business.